Video summarization
Summarize hours of video in minutes.
Our in-house vision language model describes every frame in plain English, so a day of footage reads as a timeline instead of hours of watching.
What it does.
Point it at recorded video or a live camera. One frame every few seconds is described: the people, what they wear and carry and do, the vehicles, the scene, and any text in view. The result is a timeline you can read, filter and search, with each line linked to the frame it came from.
- Every frame described
- Choose short (a sentence or two), moderate (a paragraph) or detailed (everything in depth).
- Live cameras, nothing streamed
- Add an RTSP camera and one frame is taken and summarized every few seconds, by default every 5 s.
- Scene changes caught
- Optionally take an extra frame whenever the scene changes between intervals.
- People in detail
- For each person: gender, age group, hair, upper and lower clothing, what they carry and what they're doing.
- Vehicles in detail
- Type, colour and details for each vehicle, and whether its plate is legible.
- Scene conditions
- Fire, smoke, flood, garbage, water leakage, fallen trees, broken glass, traffic jams, accidents, unattended bags, blocked exits and darkness.
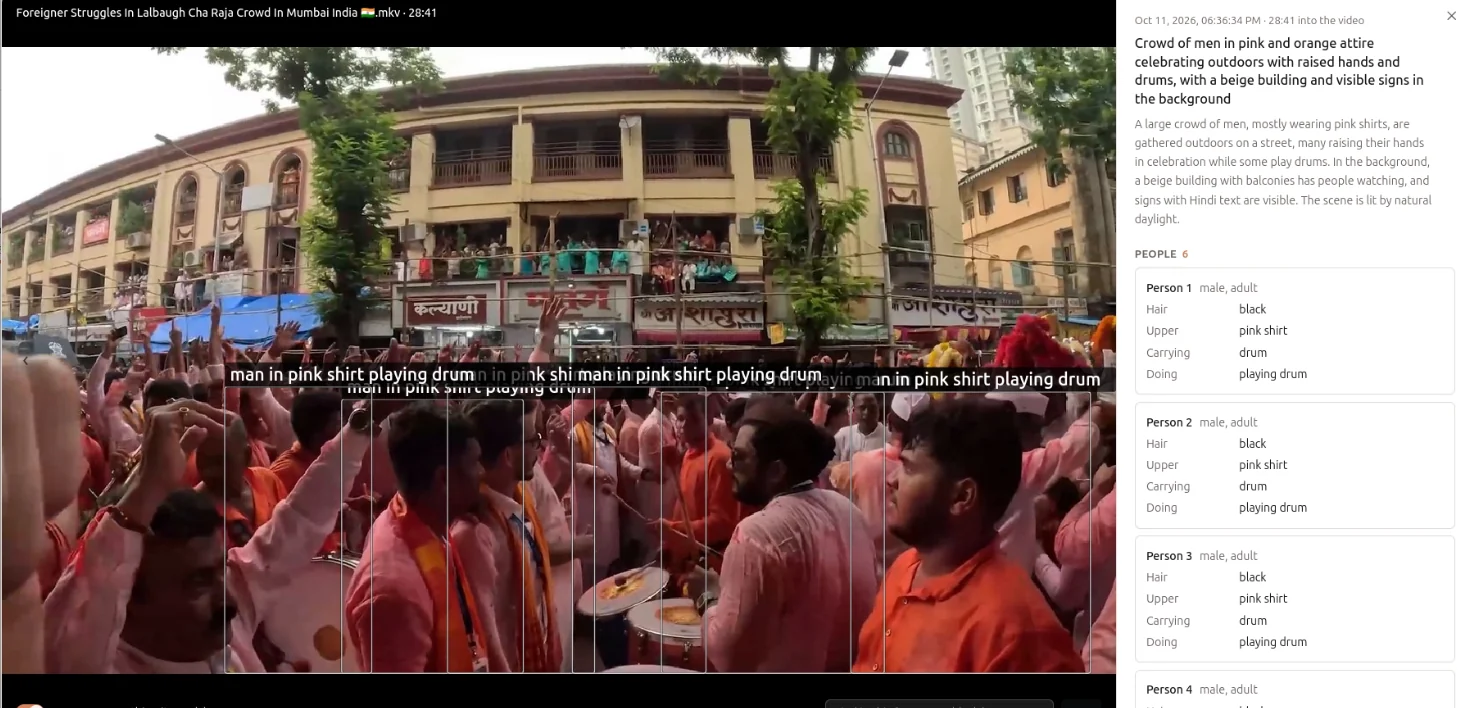
Frame detail: every person described, with boxes on everything the model saw. 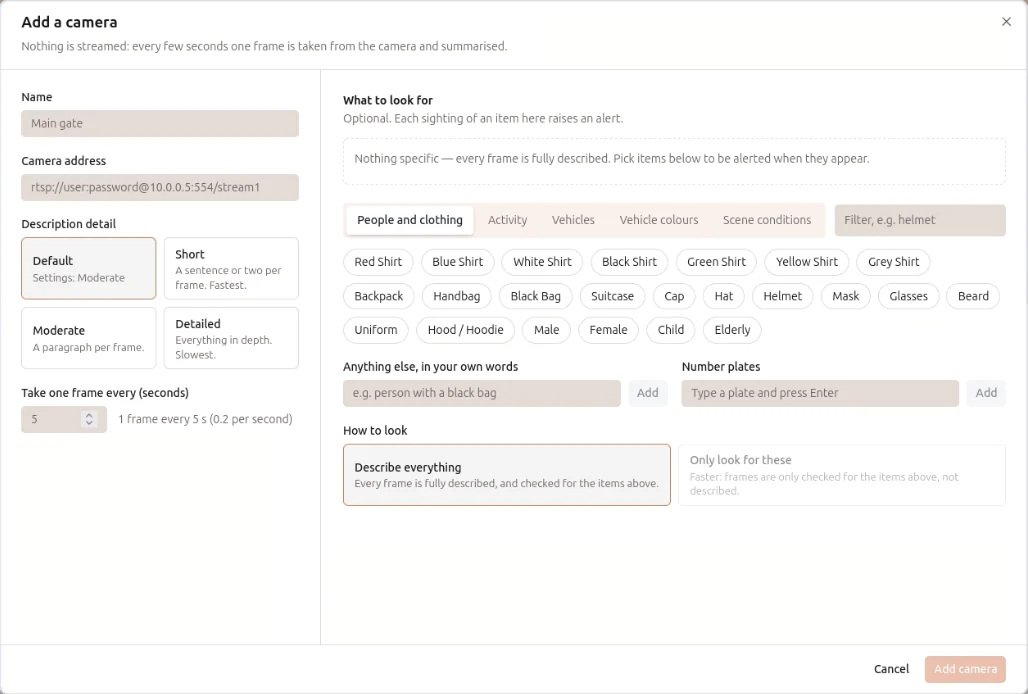
Adding a live camera: pick what to look for, or describe everything.
How it works.
- 01
Ingest
Live RTSP cameras or recorded footage, from the cameras you already have.
- 02
Detect
Every frame is analysed for the people, vehicles and objects this product looks for.
- 03
Match
Detections are compared with your watchlists, rules and zones.
- 04
Alert
Matches reach your team with the frame, the camera and the time.
On-premises or cloudInstalled on your systems, in the cloud, or both.
REST APIsIntegrate with your video analytics application and third-party software.
Your camerasWe size the hardware and recommend cameras. The cameras stay yours.